

Evidence · November 2026
Three studies. Every measurement.
Measured on Nordic’s nRF54LM20, with every method and caveat below.14
- Study 1 · Five Reflexes4.4–54nJper decisionResults ↓
- Study 2 · Eye tracking402nJper pupil estimateResults ↓
- Study 3 · MNIST digits41nJper digit · lite12Results ↓
Nordic average · seven workloads
Less energy. Less time.
Seven workloads against Neuton and TensorFlow Lite.
| Reference | Less energy | Faster |
|---|---|---|
| Neuton | 36.7× | 40.2× |
| TensorFlow Lite | 84.1× | 86.0× |
Average detailsPer-workload ratios
| Workload | Neuton time | Neuton energy | TF Lite time | TF Lite energy |
|---|---|---|---|---|
| BearingC1 | 43.5× | 41.5× | 75.1× | 77.3× |
| ToothbrushC1 | 148.1× | 145.3× | 201.8× | 209.3× |
| Magic WandC1 | 66.6× | 65.6× | 47.9× | 50.8× |
| GearboxC1 | 2.7× | 2.6× | 10.2× | 10.8× |
| TransportC1 | 22.7× | 20.3× | 45.7× | 44.2× |
| Eye trackingenergy-first · X/Y | 41.2× | 29.1× | 161.0× | 135.9× |
| MNIST digitslite12 vs Neuton · P3 vs TF Lite | 157.3× | 148.3× | 635.6× | 555.3× |
| Geometric mean | 40.2× | 36.7× | 86.0× | 84.1× |
Computed · equal-weight geometric means1
Study 1 · five Reflexes
4.4–54 nJ per decision.
Reflex software finishes first against Neuton and TensorFlow Lite on the nRF54LM20 CPU.
29.1×
less energy than Neuton
30.4×
faster than Neuton
0.54–6.65µs
per decision
Measurement setupMeasured · nRF54LM20B DK
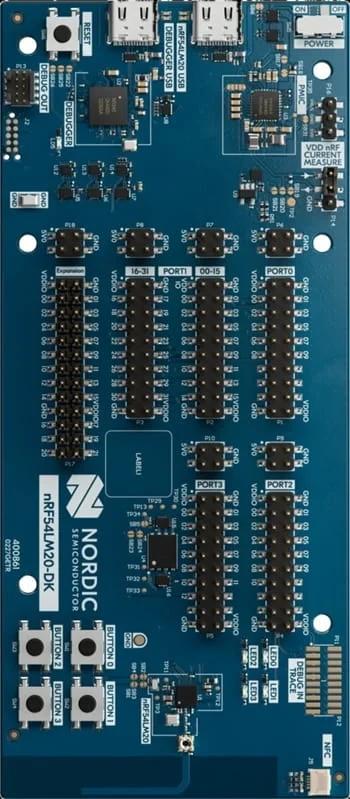
- Board
- Nordic nRF54LM20B DK
- Processor
- Arm Cortex-M33 at 128 MHz, CPU only
- Boundary
- C1: processed float features in RAM → published class
- Instrument
- Nordic PPK2, about 1 kS/s
- Protocol
- 64 phases, 784 windows, frozen artifacts
- Energy
- Measured charge × assumed constant 3.0 V
- Datasets
- 5 tasks, 6,288 rows
- Evidence
- Nordic evidence v6.3, 4 Nov 2026
Energy per decision · shared linear scale · lower is better
Bearing · Industrial condition monitoring
41.5× vs Neuton
Toothbrush · Wearables and personal care
145.3× vs Neuton
Magic Wand · Wearables and personal care
65.6× vs Neuton
Gearbox · Industrial condition monitoring
2.6× vs Neuton
Transport · Asset tracking and logistics
20.3× vs Neuton
Full results tableEvery metric · historical accuracy
Bearing
| Engine | Acc % | nJ | µs |
|---|---|---|---|
| FICUS | 100.00 | 11.00 | 1.336 |
| Neuton | 99.84 | 456.77 | 58.079 |
| TF Lite | 88.62 | 850.13 | 100.351 |
Toothbrush
| Engine | Acc % | nJ | µs |
|---|---|---|---|
| FICUS | 100.00 | 4.41 | 0.539 |
| Neuton | 100.00 | 640.98 | 79.839 |
| TF Lite | 24.00 | 923.45 | 108.789 |
Magic Wand
| Engine | Acc % | nJ | µs |
|---|---|---|---|
| FICUS | 99.84 | 12.85 | 1.572 |
| Neuton | 99.19 | 843.72 | 104.770 |
| TF Lite | 81.95 | 653.04 | 75.274 |
Gearbox
| Engine | Acc % | nJ | µs |
|---|---|---|---|
| FICUS | 98.88 | 54.44 | 6.648 |
| Neuton | 98.48 | 141.60 | 17.788 |
| TF Lite | 95.75 | 590.06 | 68.045 |
Transport
| Engine | Acc % | nJ | µs |
|---|---|---|---|
| FICUS | 100.00 | 28.82 | 3.326 |
| Neuton | 95.09 | 585.77 | 75.431 |
| TF Lite | 79.75 | 1,274.70 | 152.135 |
| Dataset | Engine | Historical accuracy (%) | Latency (µs) | Gross energy (nJ) | Idle-corrected (nJ) | Power (mW) |
|---|---|---|---|---|---|---|
| Bearing | FICUS | 100.00 | 1.336 | 11.00 | 9.36 | 8.23 |
| Neuton | 99.84 | 58.079 | 456.77 | — | 7.87 | |
| TensorFlow Lite | 88.62 | 100.351 | 850.13 | — | 8.47 | |
| Toothbrush | FICUS | 100.00 | 0.539 | 4.41 | 3.75 | 8.18 |
| Neuton | 100.00 | 79.839 | 640.98 | — | 8.03 | |
| TensorFlow Lite | 24.00 | 108.789 | 923.45 | — | 8.49 | |
| Magic Wand | FICUS | 99.84 | 1.572 | 12.85 | 10.93 | 8.18 |
| Neuton | 99.19 | 104.770 | 843.72 | — | 8.05 | |
| TensorFlow Lite | 81.95 | 75.274 | 653.04 | — | 8.68 | |
| Gearbox | FICUS | 98.88 | 6.648 | 54.44 | 46.29 | 8.19 |
| Neuton | 98.48 | 17.788 | 141.60 | — | 7.96 | |
| TensorFlow Lite | 95.75 | 68.045 | 590.06 | — | 8.67 | |
| Transport | FICUS | 100.00 | 3.326 | 28.82 | 24.71 | 8.66 |
| Neuton | 95.09 | 75.431 | 585.77 | — | 7.77 | |
| TensorFlow Lite | 79.75 | 152.135 | 1,274.70 | — | 8.38 |
Boundary, formulas and C0 energy
- Sensor
- Acquisitionoutside
- Feature extraction
- Features in RAMC1
- Preparation
- Reflex classifierC0 + C1
- Class
C1 · processed features → class · headline
E [nJ] = 3.0 V × Q [nC]
P [mW] = E [nJ] ÷ t [µs]
E_corrected [nJ] =
E_gross [nJ] − P_idle [mW] × t [µs]
P_idle is the measured idle baseline; t is the inference window.
| Dataset | FICUS (nJ) | Neuton (nJ) | TensorFlow Lite (nJ) |
|---|---|---|---|
| Bearing | 6.36 | 308.7 | 745.6 |
| Toothbrush | 2.79 | 494.0 | 803.6 |
| Magic Wand | 7.39 | 774.7 | 610.8 |
| Gearbox | 40.25 | 110.2 | 552.2 |
| Transport | 27.66 | not measured | not measured |
Memory detailsComponents only
| Reflex | Linked code + data (B) | Persistent RAM (B) |
|---|---|---|
| Bearing | 16,936 | 0 |
| Toothbrush | 7,664 | 0 |
| Magic Wand | 32,392 | 0 |
| Gearbox | 4,656 | 0 |
| Transport | 8,684 | 408 per stream |
Study 2 · eye tracking
402 nJ per pupil estimate.
Two Reflex software profiles trade speed for precision.
41–161×
faster · energy-first
29–136×
less energy · energy-first
25–45%
lower mean error · energy-first
Lowest energy and fastest: 402 nJ and 39.46 µs per X/Y update. Lower mean and median error than all three references; P95 error slightly higher than Axon and TensorFlow Lite.
| FICUS vs | NeutonNeutonNordicCPU | AxonAxonNordicNPU | TF LiteTensorFlow LiteOpen sourceCPU |
|---|---|---|---|
| Faster per X/YFICUS 39.46 µs | 41.23 times faster | 40.60 times faster | 160.98 times faster |
| Less energy per X/YFICUS 402 nJ | 96.57% less energy, 29.12 times less | 96.83% less energy, 31.58 times less | 99.26% less energy, 135.89 times less |
| Lower P95 errorFICUS 61.82 px | 22.72% lower P95 error | 5.67% higher P95 error, FICUS is worse | 5.76% higher P95 error, FICUS is worse |
Published factors · computed percentages · historical accuracy
All measurementsMeasured · historical accuracy
Lowest energy and fastest: 402 nJ and 39.46 µs per X/Y update. Lower mean and median error than all three references; P95 error slightly higher than Axon and TensorFlow Lite.
| FICUS vs | NeutonNeutonNordicCPU | AxonAxonNordicNPU | TF LiteTensorFlow LiteOpen sourceCPU |
|---|---|---|---|
| Faster per X/YFICUS 39.46 µs | 41.23 times faster | 40.60 times faster | 160.98 times faster |
| Less energy per X/YFICUS 402 nJ | 96.57% less energy, 29.12 times less | 96.83% less energy, 31.58 times less | 99.26% less energy, 135.89 times less |
| Lower mean errorFICUS 21.40 px | 45.19% lower mean error | 25.97% lower mean error | 25.32% lower mean error |
| Lower median errorFICUS 15.71 px | 55.76% lower median error | 40.63% lower median error | 39.70% lower median error |
| Lower P95 errorFICUS 61.82 px | 22.72% lower P95 error | 5.67% higher P95 error, FICUS is worse | 5.76% higher P95 error, FICUS is worse |
Each cell is the FICUS margin over that model; ember, marked worse, where FICUS loses. Speedups are the factors published with the measurements; energy and error percentages are computed from the measured table. Accuracy is descriptive: the reused INI-30 validation cohort.
| Model | Runs on | Time per X/Y(µs) | Energy per X/Y(µJ) | Active power(mW) | Mean error(px) | Median(px) | P95 error(px) |
|---|---|---|---|---|---|---|---|
| FICUS energy-firstReflex software · SR9 | CPU only | 39.461 | 0.4024 | 10.199 | 21.396 | 15.714 | 61.817 |
| FICUS accuracy-firstReflex software · TDK | CPU only | 89.641 | 0.9159 | 10.217 | 18.421 | 12.894 | 53.944 |
| FICUS previous referenceReflex software · KPrevious reference build | CPU only | 53.177 | 0.5290 | 9.948 | 24.362 | 17.954 | 69.389 |
| FICUS alternativeReflex software · TR5Not featured: its historical TEST performance missed the predefined tolerance | CPU only | 77.246 | 0.7920 | 10.253 | 18.339 | 13.070 | 53.457 |
| NeutonNordic · Neuton X/Y | CPU only | 1,626.812 | 11.7198 | 7.204 | 39.036 | 35.518 | 79.996 |
| Axon CNNNordic · Conv/Axon NPU | CPU + Axon NPU | 1,601.918 | 12.7076 | 7.933 | 28.900 | 26.468 | 58.500 |
| TensorFlow Lite CNNOpen-source framework · Conv CNN, INT8 | CPU only | 6,352.284 | 54.6883 | 8.609 | 28.650 | 26.058 | 58.451 |
Projected at 120 updates/s9Projection · zero-idle average
Projected at 120 updates/s · one 8.3 ms frame each
zero-idle average
- FICUS energy-firstCPU only0.048 mWbusy 0.5% of each frame
- FICUS accuracy-firstCPU only0.110 mWbusy 1.1% of each frame
- NeutonCPU only1.406 mWbusy 20% of each frame
- Axon CNNCPU + Axon NPU1.525 mWbusy 19% of each frame
- TensorFlow Lite CNNCPU only6.563 mWbusy 76% of each frame
Zero-idle average = measured energy per X/Y × 120, the update rate of Ganzin AURORA IIE-class eye-tracking silicon. The Cortex-M33 keeps its 128 MHz clock, which sets how fast each update finishes. Active power (10.199 mW for energy-first) is power while an update executes; the projection averages over a whole second, a different operating condition. These are arithmetic projections: measured energy per update × 120, as if nothing drew power between updates. Board idle power, wake, sensor and illumination are excluded; this is not a measurement of a complete 120 Hz product.
Study 3 · accuracy-matched MNIST
41 nJ per digit.
lite12 meets Neuton’s accuracy level, P3 fast meets Axon, TensorFlow Lite and CAIR Tsetlin Machine.
148×
less energy than Neuton · lite12
157×
faster than Neuton · lite12
+1.94pp
accuracy vs Neuton · lite12
| Reference | FICUS build | Faster | Less energy | Accuracy gain |
|---|---|---|---|---|
| Neuton | lite1294.76%computed | 157.27× | 148.29× | +1.94 pts |
| Axon CNN · NPU | P3 fast99.18%published | 43.72× | 43.89× | +0.24 pts |
| TensorFlow Lite CNN | P3 fast99.18%published | 635.60× | 555.28× | +0.24 pts |
| CAIR Tsetlin Machine | P3 fast99.18%published | 255.57× | 204.35× | +1.80 pts |
| Neuton | P3 fast99.18%published · reference | 21.34× | 17.51× | +6.36 pts |
All measurementsMeasured · validation accuracy
| Model | Runs on | Validation accuracy | Time µs | Energy nJ | Active mW | Payload KiB |
|---|---|---|---|---|---|---|
| FICUS lite12vs Neuton | M33 CPU | 94.76% | 4.83 | 41.35 | 8.57 | 36.00 |
| FICUS lite24 | M33 CPU | 97.16% | 8.19 | 69.06 | 8.43 | 72.00 |
| FICUS lite64 | M33 CPU | 98.20% | 11.29 | 110.25 | 9.76 | 192.00 |
| FICUS P3 fastvs Axon · TF Lite · Tsetlin | M33 CPU | 99.18% | 35.60 | 350.26 | 9.84 | 1,303.97 |
| Neuton | M33 CPU | 92.82% | 759.59 | 6,131.64 | 8.07 | 15.98 |
| Axon CNN | Axon NPU | 98.94% | 1,556.40 | 15,373.74 | 9.88 | 90.11 |
| TensorFlow Lite CNN | M33 CPU | 98.94% | 22,624.50 | 194,490.40 | 8.60 | 59.85 |
| Tsetlin Machine | M33 CPU | 97.38% | 9,097.30 | 71,574.37 | 7.87 | 1,130.61 |
Measured · nRF54LM20B · Nov 20261011
Historical · host CPU
A digit in 97 ns.
FICUS PURE runs on a desktop core, not a microcontroller.
21,861×
faster than ResNet-6
3,451×
faster than ViT-4
1,422×
faster than CAIR Tsetlin Machine
Host results and work per digitHistorical · computed ratios
What FICUS PURE does per digit · average over the test set
- 750pixel comparisonsworst case 2,935
- 1,063graph-index bit testsworst case 4,800
- 133ten-class score addsworst case 600
No multiply-accumulates and no floating point. ResNet-6 runs 321.6 million MACs per digit and ViT-4 28.9 million. Zero MACs still means padding, gathers, compares and integer adds.
Next step · Reflexes for Things
Measure it on your product.
Your workload, your target, against your current model.
Device makers
Pilot a Reflex
Measure two or three workloads against your current model.
Start a pilot →Investors
The full evidence pack
Executive brief, engineering appendix and KPI annex for approved investors.
Request access →Notes
- 1Average: five C1 Reflexes, eye tracking energy-first, MNIST (lite12/Neuton, P3 fast/TensorFlow Lite) · comparator/FICUS time/energy ratios, equal-weight geometric means · nRF54LM20, 128 MHz, 3.0 V · boundaries differ, accuracy never averaged · Axon untested on five Reflexes; host excluded · excluding 24%-accurate TensorFlow Lite toothbrush: 74.6× slower, 72.2× more energy.
- 2Study 1: “Ficus — Reflex cards and Instinct — Nordic evidence v6.3”, pp 1–5 · absolute KPI annex, 3.0 V · Nordic executive brief/engineering appendix, 4 Nov 2026 · nRF54LM20B DK, Cortex-M33, 128 MHz, CPU only · Nordic PPK2, about 1 kS/s · 64 phases, 784 windows · 5 tasks, 6,288 rows.
- 3C1: processed float features in RAM → preparation → published class · excludes sensing/acquisition/upstream feature extraction/shared Instinct · C0: classifier alone, preparation untimed · gross includes inference-window idle · idle-corrected subtracts measured baseline, FICUS only · power: E ÷ t, repeated calls · four tasks: 16 anchors; Transport: 163 stored rows.
- 4Study 1: frozen artifacts, unequal historical accuracy, not unseen-data accuracy/battery life · TensorFlow Lite toothbrush: 24%; excluding it: 36× slower, 37× more energy, not 50.8×/52.4× · Gearbox/Neuton: 2.7× faster, 2.6× less energy · five-task C1 geometric means, equal weights, Instinct excluded · FICUS: 8.2–8.7 mW, 0.54–6.65 µs.
- 5Measured charge × assumed constant 3.0 V · declared rail, not independently verified/traced · absolute nanojoules scale with voltage · Transport C0 Neuton/TensorFlow Lite unmeasured in pack · reported precision retained.
- 6Study 1 memory: linked code/data, persistent RAM, not totals · inputs/stack/RTOS/drivers/fixtures additional · Neuton excludes runtime/scaling · TensorFlow Lite excludes interpreter/operators, reserves 32 KiB arena · matched total flash/peak SRAM unmeasured.
- 7Study 2: FICUS eye-tracking KPI package, Nov 2026 · nRF54LM20B, Cortex-M33 at 128 MHz · CPU: Reflex software/Neuton/TensorFlow Lite; NPU: Nordic Axon · prepared event-count map → X/Y, frontends included · excludes sensor/illumination/raw-event accumulation, not camera-to-gaze power · charge × declared 3.0 V, untraced; power × time = energy · published factors, computed percentages · error: pupil-centre distance, sensor pixels · reused 5,396-row INI-30 validation, different training histories, not prospective.
- 8Energy-first SR9: P95 61.82 px, 5.7–5.8% worse than Axon (58.50 px)/TensorFlow Lite (58.45 px) · accuracy-first TDK: lower mean/median/P95 vs all three · FICUS active: 10.2 mW vs 7.2–8.6 mW, finishes 17–161× sooner · K: previous reference · TR5: lower mean/P95 than TDK; historical TEST missed predefined tolerance, unfeatured · SR9/TDK memory/placement, operation counts, quiet-floor projection unavailable.
- 9120 updates/s: arithmetic projections, energy/update × 120, hypothetical zero idle · not a complete 120 Hz product measurement · excludes board idle/wake/sensor/illumination · active 10.199 mW vs projected 0.048 mW: different conditions · clock 128 MHz, not 120 Hz · 39.46 µs/update, 0.47% busy/8.3 ms frame · rate: Ganzin AURORA IIE, Electronic Specifier, 4 Jan 2026.
- 10Study 3: “FICUS MNIST results on nRF54LM20B”, Nov 2026 · Nordic nRF54LM20B DK, Cortex-M33, 128 MHz, 3.0 V · Nordic Axon CNN: NPU; others CPU · 28 × 28 image → digit · separate firmware, identical images, different memory placements, descriptive factors · common 5,000-image validation, official test separate · lite12 94.76% vs Neuton 92.82%; P3 fast 99.18% vs Axon/TensorFlow Lite 98.94%, CAIR Tsetlin Machine 97.38% · full files: 28 comparisons/historical implementations · MNIST: LeCun, Cortes, Burges.
- 11MNIST: P3 factors published, unrounded measurements · lite12/Neuton computed, rounded table, ≈±0.1% rounding · muted P3/Neuton: published reference, not accuracy match · larger tables: lite12 36 KiB/Neuton 16 KiB; P3 1,304 KiB/TensorFlow Lite 60 KiB/Axon 90 KiB · active lite12 8.57 mW/Neuton 8.07 mW; P3 9.84 mW/others 7.87–9.88 mW · saving: time, not power · payload excludes code/runtime/working RAM · peak RAM/operation counts unavailable · full files: above-idle energy, idle power, charge, sensitivity.
- 12Host: “Updated MNIST Ficus results”, 12 Nov 2026 · AMD Ryzen 9 9950X, one thread · 16 cores · up to 5.75 GHz · AVX-512 · warm CPU · raw 28 × 28 uint8 pixels in RAM → padding/predicates/decision → class · excludes file I/O/setup/training · B1/B128: 1/128 digits/native chunk · median of five window means, not p50/p99 requests · audit 800/800: source/frozen hashes/arithmetic, no rerun · historical official 10,000 MNIST test digits · weights trained; thresholds from 5,000 validation digits.
- 13Desktop, not microcontroller; no energy/power measured · graphs: 12 Nov; references: 10 Nov, same CPU model/different cores · B1: reference 1,024 digits/FICUS 10,000, descriptive ratios · PURE accuracy: −0.46 pp vs ResNet-6, −0.28 pp vs ViT-4, +1.46 pp vs CAIR · local implementations, not all optimised runtimes · zero MACs/float still requires padding/gathers/comparisons/integer adds/memory moves · arrays, not RAM/MCU flash · PURE: new fit, 4.9× raw32 tables, not compression · Tsetlin cached-index workspace ≈502 MB.
- 14Historical accuracy: execution, not fresh generalisation · Transport 163/163: 156 known-session rows, 7 observer rows · The Nordic average spans three boundaries · one MCU family · pilots: whole-device sensing/radio/idle energy, battery life vs customer baseline · FICUS Silicon: design target until V5 measured · TensorFlow Lite: open-source framework, now published as LiteRT · Neuton/Axon NPU: Nordic.